JavaScript SEO Checklist for React and Next.js Sites
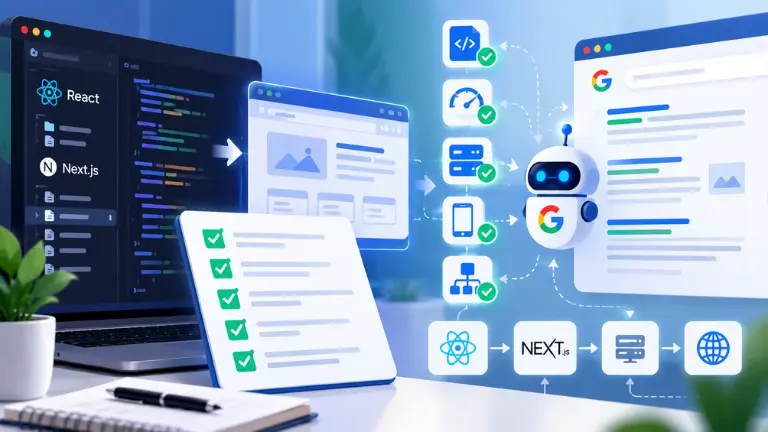
search engines need, meaning content, links, metadata, canonical tags, and status codes, should be present in the server’s initial HTML or render reliably afterward. Google can run JavaScript, but relying on that alone adds delay, risk, and blind spots with other crawlers.
In this article22 sections
This checklist covers rendering choices, links, the Next.js Metadata API, hydration issues, structured data, and testing. It is based mainly on Google’s own documentation, last updated in 2026, plus the current Next.js and React docs.
What Is JavaScript SEO, and Why Do React Sites Need a Checklist?#
JavaScript SEO is the practice of making JavaScript-powered sites easy for search engines to crawl, render, and index. React sites need a checklist because their content often depends on code running correctly, and small mistakes, such as a fragment-based route or a failed API call, can hide pages from search.
Google processes JavaScript apps in three phases: crawling, rendering, and indexing. Googlebot fetches a URL, checks robots.txt, and parses the HTML for links. Pages with a 200 status code then enter a render queue, where a headless Chromium executes the JavaScript. Google’s documentation says a page may wait in that queue for a few seconds, but it can take longer. Pages with non-200 status codes may skip rendering entirely.
Google’s JavaScript SEO basics also states that server-side or pre-rendering remains a great idea, because it makes sites faster for users and crawlers, and not all bots can run JavaScript.
Should You Use Server-Side Rendering, Client-Side Rendering, or Dynamic Rendering?#
For pages you want indexed, use server-side rendering (SSR) or static generation. Client-side rendering (CSR) can work in Google, but it adds a dependency on the render queue and on any crawler that cannot execute JavaScript. Dynamic rendering is a workaround Google no longer recommends.
| Approach | How it works | SEO implication |
| Static generation | HTML built ahead of time | Fast, complete HTML; strong default for stable pages |
| Server-side rendering | HTML built per request | Complete HTML; good for frequently changing pages |
| Client-side rendering | Browser builds content from JavaScript | Depends on rendering; weakest option for key pages |
| Hydration (SSR plus client code) | Server HTML, then React attaches interactivity | Good, provided server and client output match |
| Dynamic rendering | Bots get pre-rendered HTML, users get CSR | Google calls it a workaround, not a long-term solution |
Google’s dynamic rendering documentation recommends server-side rendering, static rendering, or hydration instead. It adds that other search engines may ignore JavaScript entirely. In Next.js, the metadata object and generateMetadata function are only supported in Server Components, so SEO-critical routes fit naturally on the server.
The JavaScript SEO Checklist for React and Next.js#
1. Put Critical Content in the Initial HTML#
Open view-source on an important page. Your main heading, body copy, product details, and internal links should be there, not just in the rendered DOM. If the HTML is an empty app shell, Google must execute JavaScript before seeing anything, which is where most indexing problems begin.
2. Use Real, Crawlable Links#
Google discovers links only when they are <a> elements with an href attribute. Avoid click handlers on buttons or divs for navigation. Use Next.js Link, which renders anchor tags, and never route with URL fragments such as #/products. Google says fragments are unreliable for crawling and recommends the History API.
3. Set Metadata With the Next.js Metadata API#
The Next.js Metadata API gives each route a title, description, and canonical, with Next.js generating the <head> tags for you. Use a static metadata export for fixed pages and generateMetadata for data-driven ones:
export async function generateMetadata({ params }) {
const { slug } = await params
const post = await getPost(slug)
return {
title: post.title,
description: post.summary,
alternates: { canonical: `/blog/${slug}` },
}
}
Three details matter. First, wrap data fetching in React’s cache so metadata and the page share one request. Second, note that for dynamically rendered pages Next.js streams metadata after the initial UI, but disables that for bots that expect metadata in the head, such as Bingbot, per its metadata documentation. Verify what Googlebot receives. Third, set the canonical in HTML. Google says not to use JavaScript to change it to something different from the original HTML, and to ensure only one canonical tag exists.
Search Savvy’s free meta tag generator is a quick way to draft titles and descriptions before adding them to your routes.
4. Return Meaningful Status Codes#
Missing pages should return a real 404, not a 200 with an error message. In single-page apps where that is hard, Google offers two fixes: redirect via JavaScript to a URL that returns a 404, or add a noindex robots meta tag to the error view. In Next.js, calling notFound() for missing data is the cleaner path.
5. Handle Robots Rules Carefully#
Do not block your JavaScript or CSS files in robots.txt. Google states it won’t render JavaScript from blocked files or on blocked pages. Also avoid shipping noindex in the original HTML and removing it with JavaScript. Google may skip rendering when it sees noindex, so the removal may never run. Next.js supports robots and sitemap file conventions, and a clean sitemap XML still helps discovery.
6. Add Structured Data in the Server HTML#
Google allows JSON-LD injected with JavaScript, but server-rendering it removes a failure point. Test every template in the Rich Results Test. Search Savvy’s schema markup generator can produce valid JSON-LD to adapt for your components.
7. Prevent Hydration Issues#
Hydration attaches React to server-rendered HTML, and the server output must match the initial client render. React’s hydrateRoot documentation says it warns about mismatches in development and can recover from some errors, but you should fix them like any other bug. Common causes include timestamps, random values, and browser-only branches such as checks on window.
The SEO concern is practical. A mismatch can make the DOM users see differ from the HTML crawlers first received, and React’s own error text notes that server HTML can be replaced with client content. Google publishes no hydration-specific ranking rule, so treat this as a reliability issue. Fix mismatches by computing client-only values in an effect after mount.
8. Lazy-Load Without Hiding Content#
Images and sections that load only after a click or unusual scroll event may never be seen. Follow Google’s lazy-loading guidelines and make sure important content appears in the rendered HTML without user interaction.
9. Fingerprint Your Static Files#
Google’s rendering service caches aggressively and may ignore caching headers, which can lead to outdated JavaScript or CSS. Content fingerprinting, such as main.2bb85551.js, avoids stale resources.
How Do You Test JavaScript SEO?#
Test with Google’s own tools first, then confirm with crawls.
- URL Inspection tool: Check the rendered HTML and screenshot for missing content.
- Rich Results Test: Confirm structured data and rendered output.
- View-source versus Inspect: Compare raw HTML with the live DOM.
- JavaScript-off check: Load the page without scripts to see what non-rendering bots receive.
- Crawler comparison: Crawl with and without JavaScript rendering and compare titles, links, and word counts.
If you want expert eyes on rendering and indexation, Search Savvy offers technical SEO services and website audit services.
What JavaScript SEO Mistakes Should You Avoid?#
- Treating “Google can render JavaScript” as proof of indexing. Rendering is queued and can fail.
- Using fragment routes. Use real URLs and the History API.
- Soft 404s. Error views that return a 200 waste crawling and confuse indexing.
- Relying on dynamic rendering long term. It adds complexity and Google does not recommend it.
- Testing only in your browser. Your cache, login state, and fast machine hide problems.
- Ignoring AI crawlers. Behaviour varies by vendor, so check each one’s documentation and your logs.
The Bottom Line#
For React and Next.js, the safest JavaScript SEO strategy is server-render or statically generate anything you want indexed, keep links as real anchors, set metadata and canonicals in HTML, return honest status codes, and test with Google’s tools after every major release. Run through this list on your ten most valuable templates first. If you would rather have a specialist review how your site renders for search and AI answer engines, Search Savvy’s AI search optimization services are a good starting point.
Frequently Asked Questions#
Is client-side rendering bad for SEO?#
Not automatically. Google renders JavaScript with an evergreen Chromium, so CSR pages can be indexed. But rendering is queued, can take longer than expected, and other crawlers may not run JavaScript, so server-rendering is safer for pages that matter.
Is dynamic rendering still recommended?#
No. Google describes dynamic rendering as a workaround, not a long-term solution, because of its added complexity. It recommends server-side rendering, static rendering, or hydration.
Can I change a canonical tag or noindex with JavaScript?#
Be careful. Google says you can inject a canonical with JavaScript, but it must match the HTML canonical, and only one tag should exist. For noindex, Google may skip rendering, so removing it with JavaScript may not work.
Do hydration errors hurt SEO?#
Google has not published a hydration-specific penalty. The risk is indirect: mismatches can change what appears after rendering compared with the server HTML, and they signal fragile code. Fix them as bugs.
Does the Next.js Metadata API work for SEO?#
Yes. It generates head tags for titles, descriptions, canonicals, and Open Graph data from Server Components. Check how streamed metadata behaves for the bots you care about, and use htmlLimitedBots if you need blocking metadata for specific user agents.
Do AI crawlers execute JavaScript?#
It varies by vendor and can change, so check each company’s documentation and your server logs. Server-rendered HTML is the safest approach because it does not depend on any crawler running your scripts.