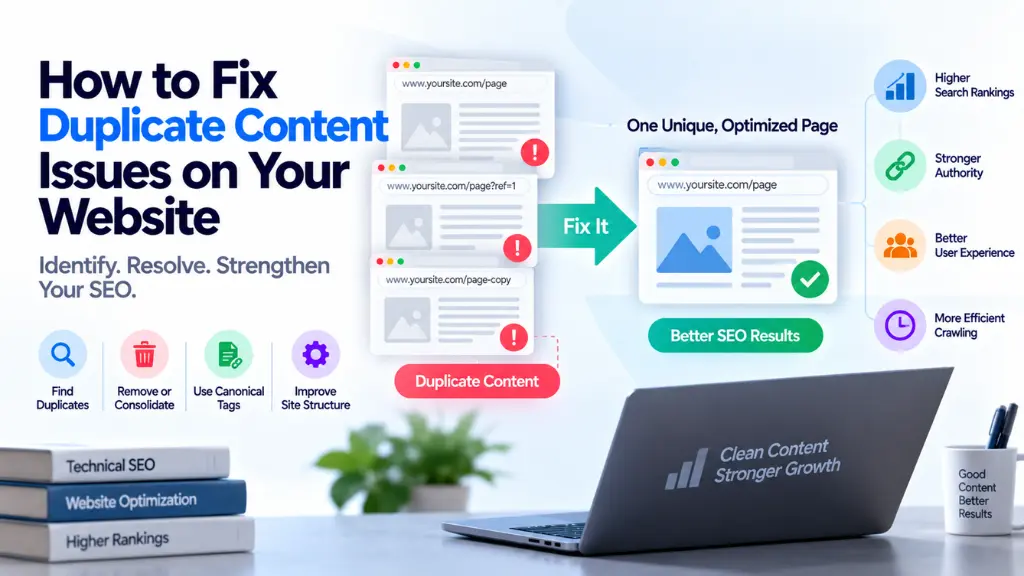
Duplicate content doesn’t get your site penalized the way many SEOs assume – but it does something arguably worse for larger sites: it splits ranking signals across multiple URLs, wastes crawl budget on redundant pages, and leaves Google to guess which version you actually want indexed. Duplicate content issues are one of the most common technical SEO problems, and also one of the most misunderstood, because the fix depends entirely on which of several different causes is behind it.
This guide walks through how to correctly diagnose duplicate content, the specific fix for each common cause – from URL parameters to HTTP/HTTPS variants to syndicated content – and how to confirm in Search Console that the fix actually worked.
What Counts as Duplicate Content?
Duplicate content is any block of substantive content that appears at more than one URL, either within your own site or across different domains, in a way that could confuse search engines about which version to index and rank. It includes both exact duplicates (the same page reachable at two URLs) and near-duplicates (pages so similar that search engines struggle to tell them apart).
Google has been explicit for years that there is no dedicated “duplicate content penalty.” Instead, when Google finds several pages with the same or very similar content, it groups them into a cluster, picks the version it considers most complete and authoritative, and shows that one in search results while filtering the rest out of view. The practical effect looks like lost traffic even without a formal penalty, because your preferred URL may not be the one Google chose.
Why Duplicate Content Hurts SEO Even Without a Penalty
- Split ranking signals. Links and engagement pointing at two different URLs for the same content divide authority that could otherwise be consolidated onto one page.
- Wasted crawl budget. Googlebot spends time crawling duplicate versions instead of new or updated pages, which matters most on large sites where crawl budget is genuinely limited.
- Unpredictable indexing. Google’s algorithm – not you – decides which duplicate URL to show, and it doesn’t always match your intended canonical page.
- Diluted authority for AI answer engines. Large language models generating AI Overviews or chat-based answers don’t respect canonical tags the way search crawlers do, so unresolved duplicate content can spread citation credit across multiple versions of the same page.
The Most Common Causes of Duplicate Content
| Cause | Example | Typical Fix |
| URL parameters (filters, sorting, tracking) | /shoes?color=red&sort=price and /shoes?sort=price&color=red | Canonical tag pointing to the clean base URL |
| HTTP vs. HTTPS or www vs. non-www | http://site.com and https://www.site.com serving the same page | 301 redirect to one preferred version |
| Trailing slash inconsistency | /page and /page/ | 301 redirect or consistent internal linking |
| Session IDs in URLs | /product?sessionid=abc123 | Server-side removal of session parameters from crawlable URLs |
| Printer-friendly or PDF versions | /article and /article/print | Canonical tag pointing to the main article |
| Syndicated or republished content | Guest post republished on a partner site | Canonical tag on the syndicated copy pointing back to the original |
| Paginated series | /blog?page=2, /blog?page=3 | Self-referencing canonical on each page – never canonicalize to page 1 |
| International/language variants | /en/, /en-gb/, /en-us/ serving near-identical content | hreflang annotations, not canonical tags |
| E-commerce product variants | Same product listed under multiple categories | Canonical tag to one primary URL, consistent internal linking |
How to Diagnose Duplicate Content Before Fixing It
Start in Search Console’s Pages report and look for the status “Duplicate without user-selected canonical.” This status means Google found multiple similar URLs and picked one on its own because you didn’t clearly specify a preference.
- Open Search Console → Pages and check the “Why pages aren’t indexed” section for duplicate-related statuses, including “Duplicate, Google chose different canonical than user” and “Duplicate without user-selected canonical.”
- For any flagged URL, run it through the URL Inspection tool, which shows exactly which URL Google currently treats as canonical and whether that matches what you intended.
- If Google’s chosen canonical disagrees with yours, work through the common causes: a missing or incorrect rel=”canonical” tag, a server misconfiguration, unauthorized syndication, or language variants missing hreflang annotations.
- Crawl your own site with a tool like Screaming Frog to find pages with duplicate title tags, meta descriptions, or near-identical body content – these often surface duplicate content issues before Search Console ever reports them.
- Check whether the same content is reachable through more than one path – category-nested URLs, faceted navigation, or old URLs left live after a migration are common culprits worth auditing directly.
Be patient with the timeline: even after the underlying cause is fixed, Google may hold pages in a duplicate cluster for up to two weeks before re-evaluating which version to show, and pages with a clear, significant difference from the rest of the cluster tend to split out faster than a small edit to an otherwise near-identical page.
Fixing Duplicate Content: Canonical Tags vs. 301 Redirects
These two are the primary tools, and choosing the wrong one for the situation is the single most common mistake in duplicate content fixes.
Use a 301 redirect when the duplicate URL should stop existing entirely and users never need to reach it directly – old HTTP versions, retired www/non-www variants, or a page that’s permanently moved. A 301 is the strongest possible signal to search engines about which URL should become canonical, because it removes the duplicate from circulation completely.
Use a rel=”canonical” tag when both URLs need to stay accessible to users, but only one should be treated as the master copy for ranking and indexing – filtered product listings, tracking-parameter URLs, or a syndicated article that needs to remain live on a partner site while pointing ranking credit back to the original.
A few implementation rules matter regardless of which method you use:
- Place the canonical tag in the <head> of the page. Google explicitly treats a canonical tag placed in the <body> as invalid and typically ignores it.
- Link internally to the canonical URL, not the duplicate. Consistent internal linking is itself a signal Google uses when deciding which version to treat as canonical.
- Don’t specify different canonical URLs for the same page through different methods – for example, one URL in your sitemap and a different one in the rel=”canonical” tag. Conflicting signals reduce Google’s confidence in any of them.
- Never canonicalize paginated pages back to page 1. Doing so tells Google that every deeper page in the series is a duplicate to be ignored, effectively hiding that content from indexing. Use a self-referencing canonical on each page in the series instead.
- Don’t use robots.txt or the URL removal tool as a substitute for canonicalization. Google may still index a URL disallowed in robots.txt without crawling its content, and the removal tool hides all versions of a URL from search rather than consolidating them.
Handling Duplicate Content from URL Parameters
Parameter-driven duplication is the most common source on e-commerce and filterable content sites: three filters can generate eight URL combinations before sorting or pagination are even added. Google retired its dedicated URL Parameters tool in Search Console years ago, stating its own crawlers had become reliable enough at inferring which parameters matter without manual configuration, so parameter handling now happens primarily through canonical tags rather than a Search Console setting.
The practical approach:
- Set a canonical tag on every filtered or sorted URL pointing to the clean, unfiltered base URL.
- Strip tracking parameters (utm_source, gclid, fbclid) from the canonical version – these should never appear in the URL a canonical tag points to.
- Enforce a consistent parameter order across your CMS so ?color=red&size=large and ?size=large&color=red aren’t treated as separate pages internally, even though the canonical tag will consolidate them either way.
- For parameters that meaningfully change content – a genuinely different product page reached through a category filter, for instance – don’t canonicalize; that’s not duplicate content, it’s a distinct page that happens to share a template.
International Content: hreflang, Not Canonical Tags
A common mistake on multilingual or multi-region sites is applying canonical tags across language or country variants the way you would for a duplicate URL parameter. That’s the wrong tool: /en-us/ and /en-gb/ pages serving near-identical content for different regions aren’t duplicates to be consolidated – they’re legitimate variants that need hreflang annotations telling search engines which version to show to which audience. Canonicalizing them into one version would remove the regional pages from search entirely, which defeats the purpose of having them.
Common Mistakes When Fixing Duplicate Content
- Canonicalizing to a non-indexable page. A canonical tag pointing to a URL that’s blocked by robots.txt, marked noindex, or returns a 404 sends a contradictory signal that Google typically ignores.
- Creating canonical chains. Page A canonicalizes to Page B, which canonicalizes to Page C. Every canonical tag should point directly to the final, indexable version.
- Treating similar pages as duplicates. Canonical tags should only apply to content that’s genuinely duplicate or near-duplicate – two different product models, even in the same category, shouldn’t canonicalize to each other just because they share a similar description.
- Expecting instant results. Because Google re-evaluates duplicate clusters over time rather than immediately, checking the URL Inspection tool the day after a fix and concluding it “didn’t work” is premature.
- Fixing the symptom without fixing the cause. Adding a canonical tag to a syndicated article helps, but if internal links across your own site still point inconsistently to both HTTP and HTTPS versions, the underlying duplication keeps generating new instances.
Frequently Asked Questions
Does duplicate content get a website penalized by Google? No. Google has stated publicly that there’s no specific penalty for duplicate content. Instead, Google clusters similar pages, selects one to show in search results, and filters the rest – which reduces visibility for the non-selected versions without being a punitive penalty.
What’s the difference between a canonical tag and a 301 redirect for duplicate content? A 301 redirect permanently sends users and search engines to a new URL and removes the old one from circulation. A canonical tag keeps both URLs live and accessible but tells search engines which one should receive ranking credit and appear in search results.
How long does it take for Google to recognize a duplicate content fix? Google may hold pages in a duplicate cluster for up to two weeks after a fix before re-evaluating which version to display, though pages with a clearer, more significant difference from the rest of the cluster tend to resolve faster.
Can duplicate content across different domains hurt my SEO? Yes, if the same content is syndicated elsewhere without a canonical tag pointing back to the original, search engines may choose the other domain’s version to rank instead – particularly if that domain has stronger authority signals.
Should I noindex duplicate pages instead of using a canonical tag? Noindex is appropriate when a page should never appear in search results at all – like an internal search results page. Canonical tags are the better choice when the page should stay indexable for users but you want ranking signals consolidated elsewhere.
Is the Search Console URL Parameters tool still useful for fixing duplicate content? No. Google deprecated the tool, citing its own improved ability to infer parameter behavior automatically. Canonical tags, consistent internal linking, and stripping tracking parameters from canonical URLs are now the standard approach.
The Bottom Line
Fixing duplicate content issues isn’t a single action – it’s matching the right tool to the right cause, whether that’s a 301 redirect for a retired URL format, a canonical tag for filtered and parameter-driven pages, or hreflang for legitimate regional variants that shouldn’t be consolidated at all. Start by identifying the pattern in Search Console’s Pages report before touching any code, since guessing at a fix without confirming the cause tends to create new inconsistencies rather than resolving the old one. For sites where duplicate content has built up across years of URL changes, migrations, or CMS defaults, Search Savvy’s technical SEO services team typically starts with exactly this kind of crawl-and-cluster diagnosis before recommending fixes, and a broader website audit can catch related indexing issues that often travel alongside duplicate content on larger sites.