Crawl Budget Waste: How to Find and Fix It on Mid-Size Websites
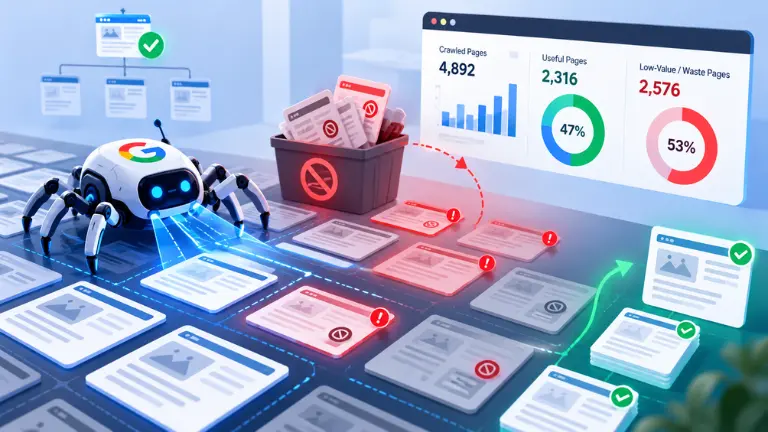
Crawl budget optimization means steering Googlebot toward the URLs you actually want indexed and away from duplicates, filter combinations, redirects, and error pages. On a mid-size site, roughly 10,000 to 500,000 URLs, the trouble is rarely that Google crawls too little overall. It is that a large share of the crawling lands on URLs that were never meant to matter.
In this article21 sections
This guide shows how to spot that waste using Google’s Crawl Stats report and server logs, which fixes are worth your effort, and which popular “fixes” Google says do little. The short version: consolidate or block low-value URL spaces, return honest status codes, keep sitemaps clean, and link important pages properly.
What Is Crawl Budget Optimization, and Does Your Site Need It?#
Crawl budget optimization is the process of making sure Googlebot spends its limited crawling time on your valuable, indexable URLs rather than on duplicates, filter variations, redirects, and errors. Google describes crawl budget as the set of URLs it can and wants to crawl, shaped by your server’s capacity and Google’s demand for your content.
Google’s own guide is aimed mainly at sites with 1 million or more unique pages that change weekly, sites with 10,000 or more pages that change daily, and sites with many URLs stuck in “Discovered – currently not indexed”. Google calls those numbers rough estimates, not thresholds. The full crawl budget guide was last updated in July 2026.
Many mid-size sites fall outside those numbers by page count but still have the problem. A 30,000-product store with filters can expose a URL space many times larger than its real inventory. Google calls this “perceived inventory,” and it is the demand factor you can influence most.
One clarification: crawling is not a ranking factor. Improving crawl efficiency helps new and updated pages get discovered faster. It does not lift rankings on its own.
What Are the Signs of Crawl Budget Waste?#
The clearest sign is that important pages take too long to be crawled or indexed while Googlebot stays busy elsewhere. Look for these patterns:
- New or updated pages take weeks to appear in the index.
- A large share of your URLs sit in “Discovered – currently not indexed” in the Page Indexing report.
- Crawl requests cluster on parameter URLs, redirects, or internal search pages instead of products, categories, and articles.
- Server logs show Googlebot requesting URLs that are not in your sitemaps.
- Response times climb or server errors appear in the Crawl Stats report.
If none of these apply, you probably do not have a crawl budget problem. For most sites, Google’s advice is simply to keep sitemaps current and check indexing reports regularly.
Where Does Crawl Budget Waste Come From?#
Most waste comes from a handful of repeatable sources. Matching your symptoms to this table speeds up diagnosis.
| Source of waste | Why it drains crawling | Typical fix |
| Faceted navigation and sort parameters | Filter combinations create near-infinite URL variations | Disallow in robots.txt, or consolidate with canonicals |
| Internal search results, session and tracking parameters | Endless URLs with no unique content | Disallow patterns in robots.txt |
| Redirect chains and redirected URLs in internal links | Each hop costs an extra request | Link directly to the final URL |
| Soft 404s and empty filter pages | Pages look valid, so Google keeps returning | Serve a real 404 or 410 |
| Duplicate URL versions (protocol, trailing slash, case) | The same page is crawled several times | Redirect and canonicalize to one version |
| Slow or error-prone servers | Google lowers its crawl capacity limit | Fix 5xx errors, improve response times |
How Do You Find Crawl Budget Waste?#
You find crawl budget waste by comparing what Googlebot actually requests with what you want it to request. Start with Google’s summary data, then confirm with your own logs.
Step 1: Read the Crawl Stats Report#
The Crawl Stats report sits under Settings in Search Console. It shows total crawl requests, total download size, and average response time, plus host status and breakdowns by response code, file type, crawl purpose, and Googlebot type.
Check three things first. Is the share of non-200 responses growing? Is average response time rising? And do the example URLs in each breakdown include parameters or old paths you did not expect? Keep in mind that Google notes the report may not count every request, so treat it as a strong sample, not a complete record.
Step 2: Confirm With Log File Analysis#
Log file analysis is the only way to see every request Googlebot makes. Search Console summarizes; your logs show the full picture. A workable process:
- Collect 30 to 90 days of raw access logs from your server, CDN, or load balancer. Include CDN logs, or cached requests will be invisible.
- Filter to Googlebot and verify the requests using Google’s documented verification methods, since user-agent strings are easy to fake.
- Group URLs by template: categories, products, articles, parameters, internal search, static resources.
- Calculate each group’s share of Googlebot requests and its status code mix.
- Compare logged URLs against your sitemaps. Note sitemap URLs Googlebot never touched and crawled URLs missing from your sitemaps.
A hypothetical example shows why this matters. Suppose a store has 200 categories, each with four filters offering five values plus an unset state. That is 6 x 6 x 6 x 6 = 1,296 variations per category, or 259,200 URLs, before parameter ordering multiplies them again. If logs show Googlebot spending most of its requests there, you have found your waste.
Step 3: Hunt for Orphan Pages#
Orphan pages are indexable URLs with no internal links pointing to them. They surface in two ways: URLs in your sitemap or logs that a fresh site crawl cannot reach through links, and old URLs Google still requests because of past links.
Google notes that pages linked closely from the homepage may be seen as more important and crawled more often. Orphans miss that internal signal. Decide for each one: link it from a relevant page if it deserves traffic, or redirect, 404, or 410 it if it does not.
Teams that want a second opinion on logs and crawl data can lean on Search Savvy’s technical SEO services or a broader website audit.
How Do You Fix Crawl Budget Waste?#
Fix the biggest URL spaces first.
Fixing Faceted Navigation Crawl Issues#
Faceted navigation crawl issues are the most common source of waste on stores and listing sites. Google’s faceted navigation guidance offers two paths. If you do not need filtered URLs indexed, prevent crawling, usually with robots.txt, and let Google reach products through individual pages and a main listing page. If you do need some indexed, use standard & separators, keep filter order consistent, and return a real 404 for combinations with no results.
Canonical tags and nofollow can help, but Google describes them as less effective long term than blocking. Filters built on URL fragments have no crawl impact at all. Stores with deep filtering often need this mapped against search demand, which is where focused ecommerce SEO support pays off: some filter pages, such as “red running shoes,” deserve indexing.
Robots.txt Optimization#
Robots.txt optimization is about blocking URL patterns that offer no search value. A simple pattern looks like this:
User-agent: *
Disallow: /*?*sort=
Disallow: /*?*sessionid=
Sitemap: https://www.example.com/sitemap.xml
A few rules keep it safe:
- Block patterns, not guesses. Test every rule against real URLs before deploying. Search Savvy’s free robots.txt generator can help you draft the file.
- Do not use robots.txt to temporarily shift budget. Google says freed capacity moves elsewhere only if you were already hitting your crawl capacity limit.
- Remember that Google cannot see a canonical or noindex tag on a blocked page.
- Avoid blocking CSS or JavaScript files that pages need to render properly.
- Do not rely on crawl-delay. Google does not process it.
Fix Status Codes, Redirects, and Soft 404s#
Return 404 or 410 for permanently removed pages. Google treats a 404 as a strong signal not to recrawl, while blocked URLs stay in the crawl queue much longer. Eliminate soft 404s, because Google keeps crawling them. Replace redirect chains with a single hop, and update internal links to point at final URLs.
Tidy Sitemaps and Speed Up the Server#
Sitemaps should list only canonical, indexable, 200-status URLs. Include accurate <lastmod> dates, and update them only when content changes meaningfully. A free sitemap XML generator from Search Savvy covers smaller sites, while larger ones usually generate sitemaps programmatically and split them by section.
On the server side, support 304 Not Modified responses so unchanged pages are not re-downloaded. Google also states that a high volume of 5xx errors or timeouts slows crawling, and rendering time counts as much as request time. Fast pages help crawling, but Google says speeding up for users should come first.
What Crawl Budget Mistakes Should You Avoid?#
- Treating every 404 as waste. Google says 4xx responses, except 429, do not waste crawl budget. Soft 404s do.
- Assuming noindex saves budget. Google must crawl a page to see the tag. It can free up crawling indirectly over time as pages leave the index.
- Faking freshness. Trivial edits and date changes add no value, and unnecessary URL versioning wastes crawling.
- Chasing crawl volume as a goal. More crawling is not better. Better-targeted crawling is.
The Bottom Line#
Crawl budget optimization on a mid-size site comes down to a few disciplined steps: measure with Crawl Stats and logs, find the largest wasteful URL spaces, block or consolidate them, and make sure the pages that remain are linked, fast, and listed in clean sitemaps. Start with one template, usually your filters, and watch Crawl Stats and log trends for a few weeks before moving on. If you want help turning logs into a prioritized fix list, Search Savvy publishes free tools and technical SEO resources that can be a starting point.
Frequently Asked Questions#
How do I check my crawl budget?#
Google does not give a single crawl budget number. Open the Crawl Stats report in Search Console to see total requests, response times, and response codes, then compare crawled URLs with your real page inventory. Server logs give the most complete view.
How big does a website need to be to worry about crawl budget?#
Google’s guidance targets sites with 1 million or more pages updated weekly, 10,000 or more pages updated daily, or many URLs stuck in “Discovered – currently not indexed.” Those figures are approximations. A smaller site with filter-generated URL sprawl can still be affected.
Does robots.txt save crawl budget?#
Yes, for the URLs it blocks, since Google will not request them. But blocking does not automatically send that capacity to other pages. Google moves it only when your site was already hitting its crawl capacity limit.
Do 404 errors waste crawl budget?#
No, not in the way many people assume. Google states that 4xx responses other than 429 do not waste crawl budget. Soft 404s, which look like normal pages but have no real content, do keep getting crawled.
Does noindex help with crawl budget?#
Only partly. Google has to crawl a page to read the noindex tag, so it still uses crawl resources. Over time, though, removing URLs from the index can let Google focus elsewhere.
Does page speed affect crawl budget?#
Yes. Faster responses let Google fetch more in the same time, and server errors slow crawling down. Google adds that making your site fast for users matters more than speeding it up for crawl coverage.