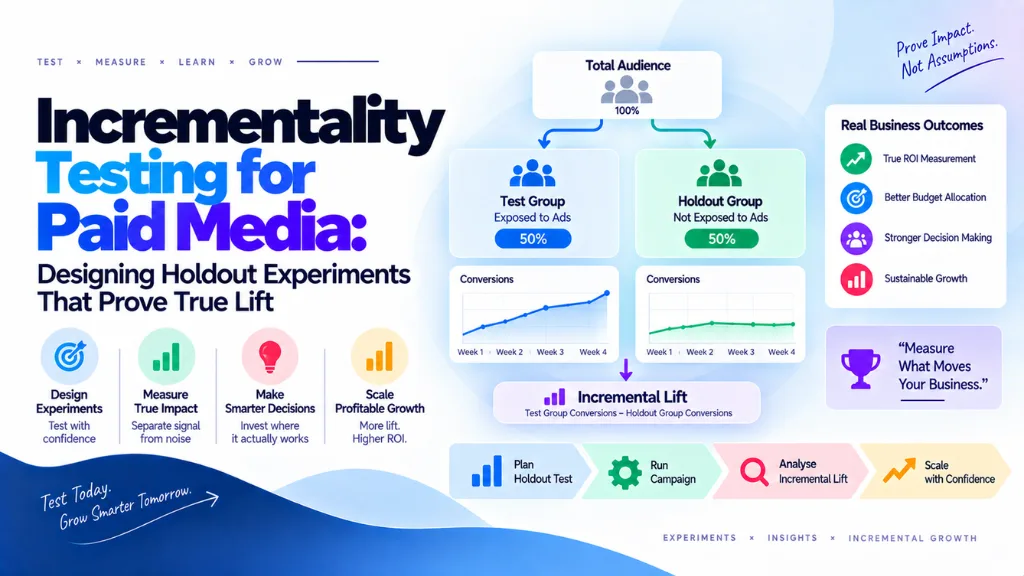

Every ad platform claims credit for conversions, and a meaningful share of those conversions would have happened anyway. A customer who already intended to buy, who searched your brand name directly, or who saw a retargeting ad after already deciding to purchase gets counted as an attributed win regardless of whether the ad actually changed their behavior. Incrementality testing for paid media answers the question platform attribution can’t: how many of those conversions were truly incremental, and how many would have occurred without the ad running at all?
A holdout experiment is the most direct way to answer that question – and it’s the same discipline Search Savvy applies before recommending any budget shift for a paid media client. In one representative example, a brand running a holdout test on a paid social campaign found customer acquisition costs of $50 per new customer in the exposed group – but the control group, which saw no ads at all, still acquired customers naturally at $70 each. The real incremental value of the campaign wasn’t the full $50 CAC platform reporting implied; it was the gap between the two, since some of that “attributed” acquisition would have happened regardless.
What Is Incrementality Testing?
Incrementality testing is a controlled experiment that compares a group exposed to advertising against a group that isn’t, in order to isolate the causal impact of a campaign rather than relying on attribution models that infer credit after the fact. The distinction matters because platform attribution – last-click, data-driven, or otherwise – measures correlation between exposure and conversion, while incrementality testing measures whether the ad actually caused the conversion to happen.
This has become a boardroom priority rather than an analytical curiosity in 2026, driven by continued signal loss from privacy regulation, the cancellation of Google’s Privacy Sandbox cookie-replacement effort, and the growing dominance of AI-driven, black-box bidding algorithms that make it harder to trust platform-reported performance at face value. When the measurement layer itself becomes less transparent, a ground-truth experiment matters more, not less.
How Is Incrementality Testing Different From a Platform Lift Study?
The key difference is data ownership. On-platform lift studies, such as Meta’s Conversion Lift tool, rely on the platform’s own data and randomization logic. True incrementality testing, run independently against a brand’s own first-party transaction data, avoids depending on any single platform’s black-box methodology – which matters most when the question being asked is cross-channel, comparing one platform’s real contribution against another’s.
Why Platform Attribution Overstates Performance
Every platform’s default measurement is structurally biased toward claiming credit. A retargeting campaign shown to users who already added a product to their cart will report strong conversion rates, because those users were highly likely to convert regardless of the ad. Branded search campaigns face the same issue – someone searching a company’s name by name has typically already decided to purchase, so measuring branded search performance against a hypothetical “no ads” baseline consistently reveals a smaller incremental contribution than platform dashboards suggest.
This is precisely the gap holdout testing is built to close: by removing exposure entirely from a representative slice of the audience and comparing outcomes, the resulting difference reflects the campaign’s actual causal effect rather than the platform’s self-reported credit.
Choosing the Right Holdout Method for Your Budget
Not every business can or should run the same style of incrementality test. The right method depends heavily on spend level and audience size, and forcing a method built for enterprise budgets onto a smaller account usually produces unreliable, noisy results.
| Method | Best Fit | Typical Threshold |
| Ghost ads / small-cell geo test | Smaller accounts without enough volume for platform-native lift tools | Under roughly $50,000/month in paid social spend |
| Platform-native lift tools (Meta Conversion Lift, Google Conversion Lift) | Mid-size accounts with sufficient reach | Meta recommends a minimum audience of 200,000, typically holding back 10% as control |
| CRM-based Conversion Lift / independent holdout | Larger accounts needing first-party-verified results | Generally above $250,000/month in paid spend |
| Synthetic controls / causal-impact modeling | Situations where randomization is politically or technically impossible | Used as a fallback, not a first choice |
Synthetic controls and causal-impact-style models are useful when a true holdout isn’t feasible – the audience can’t be randomized, or volume is too low for a clean experiment – but they lean more heavily on modeling assumptions than a genuine randomized holdout does. Treat their output as directional unless the historical pre-period fit and sensitivity checks are genuinely persuasive.
Avoiding Geo Holdout Bias
Geographic holdout tests, where ads are paused in selected cities or regions rather than for specific users, introduce a risk that’s easy to overlook: choosing markets with unusual characteristics can bias the entire result. Testing in a college town during summer break, a tourist destination during peak season, or a city where a competitor happens to be running an aggressive campaign at the same time can all distort the comparison in ways that have nothing to do with your own advertising’s real effect.
The safeguards are straightforward but easy to skip under time pressure: run tests during representative periods rather than unusual seasonal windows, use sufficiently large and properly randomized samples, and replicate important tests multiple times before making a major budget decision on the result. One test produces a single data point; several tests showing a consistent pattern produce the confidence a real budget shift deserves.
Scaling Incrementality Testing: Rolling Holdouts and Cross-Channel Design
At meaningful spend levels – commonly cited around $1 million or more per month in paid media – holdout testing stops being a one-off experiment and becomes standing measurement infrastructure. Large advertisers typically run holdouts on a recurring quarterly cadence per channel at minimum, and some maintain a persistent 5% to 10% rolling holdout group that’s continuously suppressed and compared against exposed users, producing near-real-time incrementality tracking rather than isolated point-in-time estimates.
At this scale, the relevant question also changes. Instead of asking whether one channel alone drives incremental revenue, the more useful question becomes what that channel’s incrementality looks like given the rest of the media mix already running simultaneously. Answering that requires cross-channel holdout design – geo tests where entire markets are blacked out across all paid channels at once – which is operationally more complex to run but produces a far more accurate picture of how channels interact than testing one channel in isolation while others continue running unchanged. Marketing mix modeling can help finance and leadership assess channels in aggregate, but a well-designed holdout supplies the causal ground truth that calibrates and validates those broader models.
A Step-by-Step Framework for Designing Your First Holdout Test
- Define the hypothesis precisely before designing anything. Are you testing the incremental value of one specific campaign, or the total incremental value of all paid advertising against running none at all? These require different designs.
- Choose the method that matches your spend and audience size, using the thresholds above as a starting guide rather than defaulting to whichever tool your platform interface happens to surface first.
- Randomize the holdout properly. For geo tests, avoid markets with seasonal, competitive, or demographic quirks that could bias the comparison independent of your own campaign.
- Run the test for a sufficient duration to capture a representative period rather than an unusually quiet or unusually active window.
- Replicate before acting on major budget decisions. A single test result is a data point; a consistent pattern across repeated tests is what justifies reallocating significant spend.
- Feed results back into ongoing measurement, treating incrementality testing as recurring infrastructure that recalibrates attribution and mix models over time, not a single project with a defined end date.
Search Savvy builds this kind of testing discipline into its performance marketing services, designing holdout experiments sized to a client’s actual spend and audience rather than defaulting to whichever platform tool is easiest to switch on. For teams running Google Ads campaigns alongside social, this also means coordinating the geo or user-level design across platforms rather than testing each channel’s incrementality in isolation.
Common Mistakes in Incrementality Testing
- Trusting platform-reported lift as ground truth. On-platform lift studies use the platform’s own data and randomization logic, which introduces a conflict of interest when the same platform is being measured against a “no ads” baseline.
- Choosing geo markets without checking for bias. Seasonal events, competitor activity, or unusual demographics in a test market can distort results independent of the campaign being tested.
- Running a test once and treating the result as final. A single holdout test is one data point; major budget decisions deserve replication across multiple test periods.
- Forcing a large-account testing method onto a small account. User-level lift tools built for high-volume advertisers produce unreliable, noisy results when applied to accounts without sufficient audience size.
- Testing channels in isolation at scale. Once media spend reaches a meaningful level across multiple channels, testing one channel while ignoring the others running simultaneously misses how channels actually interact.
The Bottom Line
Incrementality testing for paid media exists to answer a question platform dashboards structurally can’t: how many conversions actually happened because of the ad, rather than alongside it. A well-designed holdout experiment – sized correctly for your spend, randomized to avoid geo and seasonal bias, and replicated before major decisions – provides the causal ground truth that attribution models and marketing mix models alike depend on for calibration.
The practical next step is running one properly designed holdout test on your highest-spend channel before making your next major budget reallocation, rather than trusting platform-reported ROAS at face value. Search Savvy’s paid media measurement work builds holdout testing directly into ongoing paid media management, so budget decisions are backed by causal evidence rather than a single platform’s self-reported credit.
Frequently Asked Questions
What is incrementality testing in paid media? It’s a controlled experiment that compares a group exposed to advertising against a group that isn’t, isolating the actual causal impact of a campaign rather than relying on attribution models that infer credit after a conversion happens.
How is incrementality testing different from platform attribution? Platform attribution measures correlation between ad exposure and conversion, often overstating credit for conversions that would have happened anyway. Incrementality testing measures causation directly, using a genuine holdout group that received no ad exposure as the comparison point.
What’s the minimum spend needed to run a holdout test? It depends on the method. Smaller accounts under roughly $50,000 a month in paid social spend typically use ghost ads or small-cell geo tests, while platform-native tools like Meta’s Conversion Lift generally require a minimum audience of around 200,000 users to produce statistically reliable results.
Why do geo holdout tests sometimes produce misleading results? Choosing test markets with unusual characteristics – a college town during summer break, a tourist destination during peak season, or a region where a competitor is running an aggressive campaign – can bias the comparison in ways unrelated to the advertising being tested.
How often should incrementality testing be run? It should be treated as ongoing measurement infrastructure rather than a one-time project. Larger advertisers commonly run quarterly holdouts per channel at minimum, and some maintain a persistent rolling holdout group for near-continuous incrementality tracking.
Can incrementality testing replace marketing mix modeling? No, they serve complementary purposes. Marketing mix modeling helps assess channels in aggregate across a full historical dataset, while a well-designed holdout test supplies the causal ground truth that calibrates and validates those broader models rather than replacing them.